Three sounds, one spot The tongue tip sits in the same region for l, r and n. What differs is where the air goes: around the sides, over the top, or out through the nose. Mixing them up is not a listening problem — these three gestures were never practised apart.
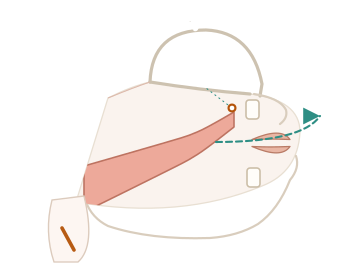
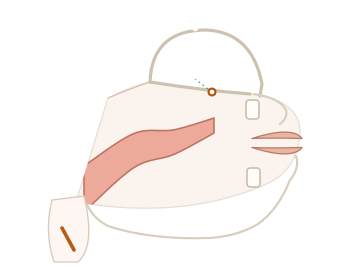
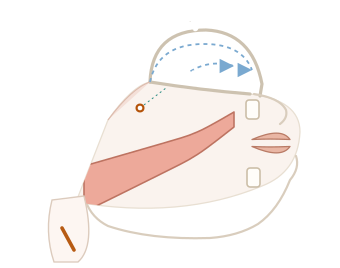
Three paths for the air
The tip is near the ridge in all three; only the exit differs.
/l/ — tip pressed, air escapes at the sides
Press the tip against the alveolar ridge (same spot as /d/) and keep it there. Air flows around both sides of the tongue. In final position (full) the tip may relax and the back of the tongue rises, which sounds almost vocalic.
/r/ — tip floating, touching nothing
The tip curls up without contacting the ridge; the middle of the tongue dips into a groove and the lips round slightly. The tip must never touch the roof of the mouth — contact turns it into /l/ or /d/.
/n/ — tip pressed, air goes through the nose
The tip presses the ridge as for /l/, but the mouth is fully sealed and air exits through the nose. Pinch your nose and /n/ stops immediately — a reliable self-check.
Articulation (side view)
One speaker, one instant: tongue position and lip shape only. The amber circle marks what to look at; the caption says how it differs from the sound it is usually confused with.
Spelling: three stable letters, one unstable sound
l, r and n map onto letters almost one to one. What actually trips people up is the two kinds of l, and three combinations where a letter is silent.
Tongue tip on the ridge behind the teeth, air out over the sides. This is the l most languages have, so word-initial l is not the problem.
Dark l: the back of the tongue lifts as well, and the sound ends in something close to an /o/. Learners either replace it with the clear l or drop it entirely — which is how milk turns into /mɪok/.
The English r touches nothing at all. It is neither the Mandarin r (a fricative, far too noisy) nor a Spanish trill. This is where the page is easiest to get wrong: substituting the Mandarin sound gives an audible scrape.
w before r, k before n, g before n — all silent. Together the three patterns cover dozens of high-frequency words.
Final -le writes no vowel but takes a syllable of its own (/ˈteɪ.bl̩/). /ˈteɪ.bəl/ is fine; /ˈteɪb/ has lost a syllable.
Why they merge
If your first language does not contrast these three at the same place, they collapse into one.
/l/ becomes /r/, or the reverse
Everything hinges on contact. /l/ must touch the ridge; /r/ must not touch anything. Many learners touch for both (both become l) or touch for neither (both become r).
Self-check: /l/ should give a clear sense of contact; /r/ should give none at all. If both feel the same, one of them is wrong.
Final /l/ dropped
If your language does not allow /l/ as a coda, the final l tends to vanish or turn into a vowel. English requires it — though the tip may relax and the tongue back may rise.
The clips here put l word-initially (glass, line, lamp); compare that contact with the l in light.
/n/ and /l/ not distinguished
Same place, same voicing; the only difference is nasal versus lateral airflow. Pinch your nose: /n/ disappears, /l/ does not.
Japanese speakers often merge these into a single sound (the ら-row), because Japanese does not contrast r and l. This is not a hearing failure — the contrast simply is not in the native inventory.
/r/ produced as a uvular trill
Spanish, French and German r lives in the throat; English r lives at the tongue. English r does not trill and does not rasp — it is an approximant, close to a vowel.
Any friction or vibration in the throat means it is not the English r. English r is 'tongue floating, throat completely relaxed'.
Word list
27 words grouped by where the sound sits in the word. Click a word to hear it. These are recorded as separate words, not cut out of the sentences above — a word cut from a sentence carries its neighbours' transitions and always sounds muddier. All three groups use the same speaker, so what changes between them is position, not voice.
Word-initial9
Word-medial9
Word-final9
There is no r in the word-final group: in non-rhotic (British) accents, a final r is not pronounced — car is /kɑː/. Some of this page's speakers are British, so an r-final word would give you a final r you cannot hear, which is not a mistake, just a different accent.
Corpus and acoustic measurements
Click any word in a sentence to play from that word. The pale band over the waveform marks the measured boundary of the target word.
Per-token data
Every number below is measured directly from the audio, not hand-annotated.
| Token | Accent | Sex | Target | Word length | l / r / n length | F0 | Pitch range | HNR |
|---|
How the numbers were produced
Every figure on this page can be recomputed from the method below.
Corpus: 12 English sentences synthesised by a TTS engine in 4 American voices (two male, two female), each containing one target word beginning with /l/, /r/ or /n/. Audio is 22.05 kHz mono at 64 kbps, each clip running 1.2 s before and 1.5 s after the target word.
Word boundaries: taken from the engine's WordBoundary timestamps and corrected for the constant offset between the engine clock and the audio start (estimated per item). The target word is shaded on the waveform.
Phoneme boundaries: measured boundaries from forced alignment with the MMS_FA acoustic model. The alignment frame span of every character is kept, and a dynamic program maps the character sequence onto the phoneme sequence (th→θ, ng→ŋ, ck→k and similar), placing each boundary at the middle of the transition between characters, with 100% coverage of the word. Temporal resolution is the model frame, 20 ms; because each boundary sits on the midpoint between neighbouring character spans, the effective resolution is about 10 ms.
This changed on 2026-10-19: the previous method looked the word up in the CMU dictionary and distributed the word duration across phonemes by class-specific weights, which measures word length rather than phoneme length. On the vowel pairs it inverted the long/short ordering outright, so the whole chain was moved to acoustic alignment.
Pitch: Praat autocorrelation (to_pitch), 10 ms frame shift, search range narrowed adaptively to the speaker's range and octave errors removed. 'Pitch range' is max minus min F0 within the word.
Harmonicity: Praat's to_harmonicity_cc. l, r and n are all voiced, so this column sits well above the voiceless consonants and varies little across the three — which is exactly the point: they share a voice source and differ only in the air path.